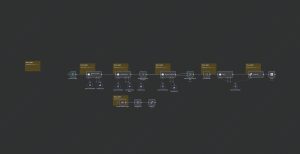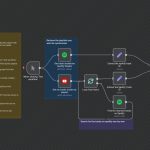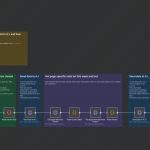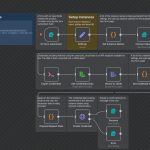
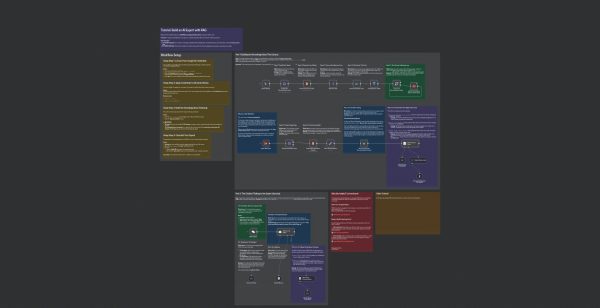
This n8n workflow automates the process of indexing the official n8n documentation to create a dynamic, in-memory knowledge base and deploys a retrieval-augmented generation (RAG) chatbot. The system fetches all documentation links, processes and chunks the content, and stores text embeddings in a vector store. Users can then interact with the AI chatbot via a web interface to ask questions about n8n, with responses generated solely from the indexed documentation, ensuring accuracy and reliability.
### Workflow Breakdown:
1. **Documentation Indexing:**
– Initiated manually to scrape the entire n8n documentation site.
– Fetches the main page, extracts all relevant links, and filters for documentation pages.
– Each page is fetched, cleaned, and split into smaller chunks.
– Embeddings are generated for each chunk using Google’s Gemini models.
– Embeddings, along with the text, are stored temporarily in an in-memory vector store.
– Duplicate content and links are removed to optimize performance.
2. **Knowledge Base Construction:**
– The indexing process is designed to run once (or periodically), building a comprehensive vector database of the documentation.
3. **Interactive Q&A Chatbot:**
– The user can ask questions through a public webhook-enabled chat interface.
– The system converts the question into a vector, searches the vector store for the most relevant chunks.
– The relevant contextual information is used by an AI model (Gemini 2.5 Flash) to generate precise, documentation-based responses.
### Use Cases:
– Building an AI assistant that provides accurate, up-to-date information from technical documentation.
– Automating the creation of FAQ or support bots for developer platforms.
– Creating an educational tool for learning n8n workflows and nodes.
This workflow is ideal for teams maintaining extensive documentation or user guides, ensuring consistent and reliable information delivery through automation.