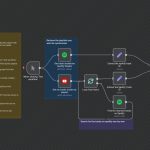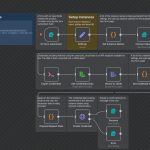
This n8n workflow automates the monitoring of Kubernetes pod CPU usage and sends timely alerts to Slack. Running every 5 minutes, it queries Prometheus for high CPU utilization across pods. If multiple pods from the same application exceed a set threshold, it groups the alerts for that app and sends a formatted message to a designated Slack channel. The workflow includes steps for transforming Prometheus data into actionable insights, distinguishing between individual pod spikes and grouped app-wide spikes, and ensuring prompt notification for efficient incident response. This setup is ideal for DevOps teams aiming to keep a close watch on Kubernetes performance and quickly act on resource bottlenecks.
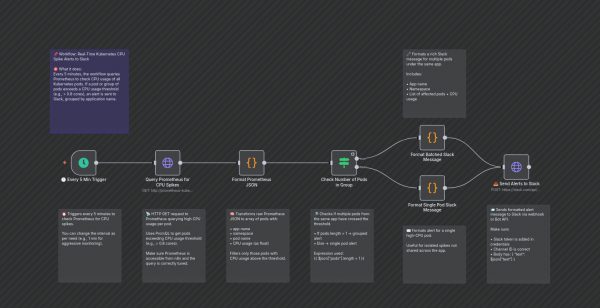
Kubernetes CPU Spike Alerts to Slack
| Node Count | 11 – 20 Nodes |
|---|---|
| Nodes Used | code, httpRequest, if, scheduleTrigger, stickyNote |